Je bent je ingevulde velden bij deze pagina aan het verwijderen. Ben je zeker dat je dit wilt doen?
You are erasing your filled-in fields on this page. Are you sure that is what you want?
Nieuwe Versie BeschikbaarNew Version Available
Er is een update van deze pagina. Als je update naar de meest recente versie, verlies je mogelijk je huidige antwoorden voor deze pagina. Hoe wil je verdergaan ?
There is an updated version of this page. If you update to the most recent version, then your current progress on this page will be erased. Regardless, your record of completion will remain. How would you like to proceed?
In this section we will define a function that assigns to each square matrix \(A\) a scalar output called the determinant of \(A\). We will
denote the determinant of \(A\) by \(\det {A}\). For a matrix with real number entries, the output of the determinant function will always be a
real number.
One important property of the determinant is its connection to matrix inverses. We will find that a matrix \(A\) is singular if and only
if \(\det {A}=0\).
Geometrically speaking, the determinant of a matrix of a linear transformation is the factor by which the area (or volume or
hypervolume) is scaled by the transformation.
Cofactor Expansion Along the Top Row
To start from the beginning, let us define the determinant of a \(1\times 1\) matrix.
Let \(A=\begin{bmatrix}a\end{bmatrix}\). Define the determinant of \(A\) by \(\det {A}=a\).
It is important to note that this definition is consistent with our goal of making a
connection between determinants and invertibility. Observe that \(A^{-1}=\begin{bmatrix}a^{-1}\end{bmatrix}\) exists if and only if \(a\neq 0\).
Now we proceed to \(2\times 2\) matrices. According to Formula ??, the inverse of a nonsingular matrix \(A=\begin{bmatrix}a&b\\c&d\end{bmatrix}\) is given by
Note the distinction between the square bracket notation associated with the matrix \(\begin{bmatrix}a&b\\c&d\end{bmatrix}\)
and the vertical bar notation \(\begin{vmatrix}a&b\\c&d\end{vmatrix}\) used to denote the determinant in expression (1).
We will now reiterate several important features of this definition and introduce some vocabulary:
The coefficients \(a\), \(b\) and \(c\) are the entries of the first row of matrix \(A\). Coefficients in the formula follow an alternating
sign pattern: \(+a\), \(-b\), \(+c\). This pattern will persist in the determinant formulas for determinants of larger matrices.
When using equation (??), we compute determinants of three matrices:
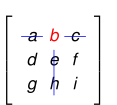
These matrices are called minor matrices. To form each minor matrix, cross out the row and column that the
corresponding coefficient is in. For example, the minor matrix corresponding to coefficient \(b\) is found by crossing out the
row and column that \(b\) is in.
The process for finding the determinant described in Definition 6 is referred to as a cofactor expansion along the top
row.
We are starting to observe a certain pattern in the process of computing the determinant. This pattern will persist for larger
matrices. Let’s take a look at a \(4\times 4\) matrix.
As you watch the video below, pay particular attention to the same patterns as you saw in the case of \(3\times 3\) matrices: the
alternating sign pattern and the process of forming minor matrices.
We will use the entries in the top row as coefficients in front of \(3\times 3\) determinants. As before, we will use the alternating sign
pattern for the coefficients:
\[+(4), -(-1), +(2), -(1)\]
Just like in the case of a \(3 \times 3\) matrix in Example 4, each of the smaller determinants is obtained by crossing out the row and the
column where the coefficient is located.
We defined the determinant of a matrix in terms of cofactor expansion along the top row. We will now see what happens
when we expand along the first column instead. We will refer to this process as cofactor expansion along the
first column. Surprisingly, both expansions yield the same result. To illustrate this, let’s revisit Examples 4 and
11.
In Example 4 we found that \(\det {A}=0\). Let’s try to mimic what we did earlier, but instead of expanding along the first row, we will
expand along the fist column.
In Example 11 we found that \(\det {A}=-58\). We will now try to expand along the fist column.
When computing determinants of the four \(3\times 3\) matrices below, try different approaches. You might want to expand along the first
row for some of them, and along the first column for others. Looking for where zeros are located will help you decide what to
try.
In Example 13 and Exploration we were careful not to claim at the outset that we were finding the determinant
of the matrix by cofactor expansion along the first column; we merely observed that the resulting value was
equal to the determinant. It is possible to prove that both expansions produce the same result (Theorem ??).
Therefore the determinant of a matrix can be defined in terms of cofactor expansion along the first row or
column.
Cofactor Expansion Along Any Row or Column
We originally defined the determinant of a matrix via expansion along the top row of the matrix. We later observed that
expansion along the first column produces the same result. It turns out that the value of the determinant can be
computed by expanding along any row or column. This result is known as the Laplace Expansion Theorem
(??).
When expanding along an arbitrary row or column, we will continue to follow the two patterns we observed earlier.
The alternating sign pattern for coefficients will follow the checkerboard pattern below.
Follow the rules described above to expand along the second row. Compare your result with the determinant you found in
Example 11.
The second row has the advantage over other rows in that it contains a zero. This will simplify our calculations. Following the
checkerboard sign pattern along the second row we get
This answer is the same as the answer we got using expansion along the first row in Example 11.
It is clear that having zeros as entries in the matrix reduces the number of computations necessary to find the determinant.
The following example demonstrates how to use zeros to our advantage.
The fourth column contains the most zeros, so we will expand along that column. The \((3, 4)\)-entry is the only non-zero entry in the
fourth column. Following the checkerboard pattern, we see that the sign in front of \(-5\) is a minus.
We initially introduced the determinant of a matrix via cofactor expansion along the top row. We later observed that cofactor
expansion along any row or column produces the same result. We have to be careful, however, not to use a few examples as
“proof" that all cofactor expansions are equivalent. Such claims need to be carefully supported with general proofs.
Unfortunately, in this case, the proofs are tedious and conceptually unenlightening. An interested reader can find them in
Tedious Proofs Concerning Determinants.
Determinants of Some Special Matrices
We know that we can find the determinant of a matrix by cofactor expansion along the top row or the first column. (See
Theorem ?? of Tedious Proofs Concerning Determinants for proof.) This property gives rise to a useful result.
Let \(A\) be a
square matrix, then
\[\det {A^T}=\det {A}\]
See Practice Problem .
As we observed earlier, having zeros in a matrix makes it easier for us to compute its determinant. Recall that that a square
matrix is upper-triangular if all of the entries below the main diagonal are zero. Similarly, a square matrix is called
lower-triangular if all of the entries above the main diagonal are zero. Together, upper and lower triangular matrices are
categorized as triangular matrices.
If \(A\) is a triangular matrix, then \(\det {A}\) is equal to the product of its diagonal entries.
We proceed by induction on \(n\), where \(A\) is an \(n\times n\) matrix. It is easy to see that this result holds for \(n=1, 2\). Suppose that the result holds for \((n-1)\times (n-1)\)
triangular matrices. We need to show that it holds for \(n\times n\) triangular matrices.
Suppose \(A=[a_{ij}]\) is a triangular matrix. Then, with the exception of \(a_{11}\), the entries in the first row (or column) of \(A\) are guaranteed to be
zeros. We will take advantage of these zeros and expand along the first row (or column) of \(A\). As we do so, we obtain a single
product of \(a_{11}\) and the determinant of a minor matrix obtained by crossing out the first row and column of \(A\). But this minor \((n-1)\times (n-1)\) matrix
is also a triangular matrix with diagonal etries \(a_{22}, a_{33},\ldots , a_{nn}\). By induction hypothesis, its determinant is equal to the product of its diagonal
entries, \(a_{22}\cdot a_{33}\cdot \ldots \cdot a_{nn}\). Therefore
As an immediate consequence of this theorem, we have the following result.
Let \(I\) be the identity matrix, then
\[\det {I}=1\]
We first introduced block matrices in Block Matrix Multiplication. Matrices of the form \(\begin{bmatrix}A & C\\O& B\end{bmatrix}\) and \(\begin{bmatrix}A & O\\D& B\end{bmatrix}\), where \(A\), \(B\) are square matrices and \(O\)
is the zero matrix, are said to be block triangular. The following theorem makes it easy to compute determinants of such
matrices.
Consider block triangular matrices \(\begin{bmatrix}A & C\\O& B\end{bmatrix}\) and \(\begin{bmatrix}A & O\\D& B\end{bmatrix}\), where \(A\) and \(B\) are square matrices. Then
Write \(T=\begin{bmatrix}A & C\\O& B\end{bmatrix}\) and proceed by induction on \(k\), where \(A\) is \(k\times k\). If \(k=1\), then the result follows from cofactor expansion along the first column. In
general, let \(S_i(T)\) denote the matrix obtained from \(T\) by deleting row \(i\) and column 1. Then the cofactor expansion along the first
column is
where \(i=1,2,\dots , k\), \(S_i(A)\) denotes matrix \(A\) with column 1 and row \(i\) deleted, and \(C_i\) denotes matrix \(C\) with with row \(i\) deleted.
Since \(S_i(A)\) is a \((k-1)\times (k-1)\) matrix, by the induction hypothesis,